What we learned
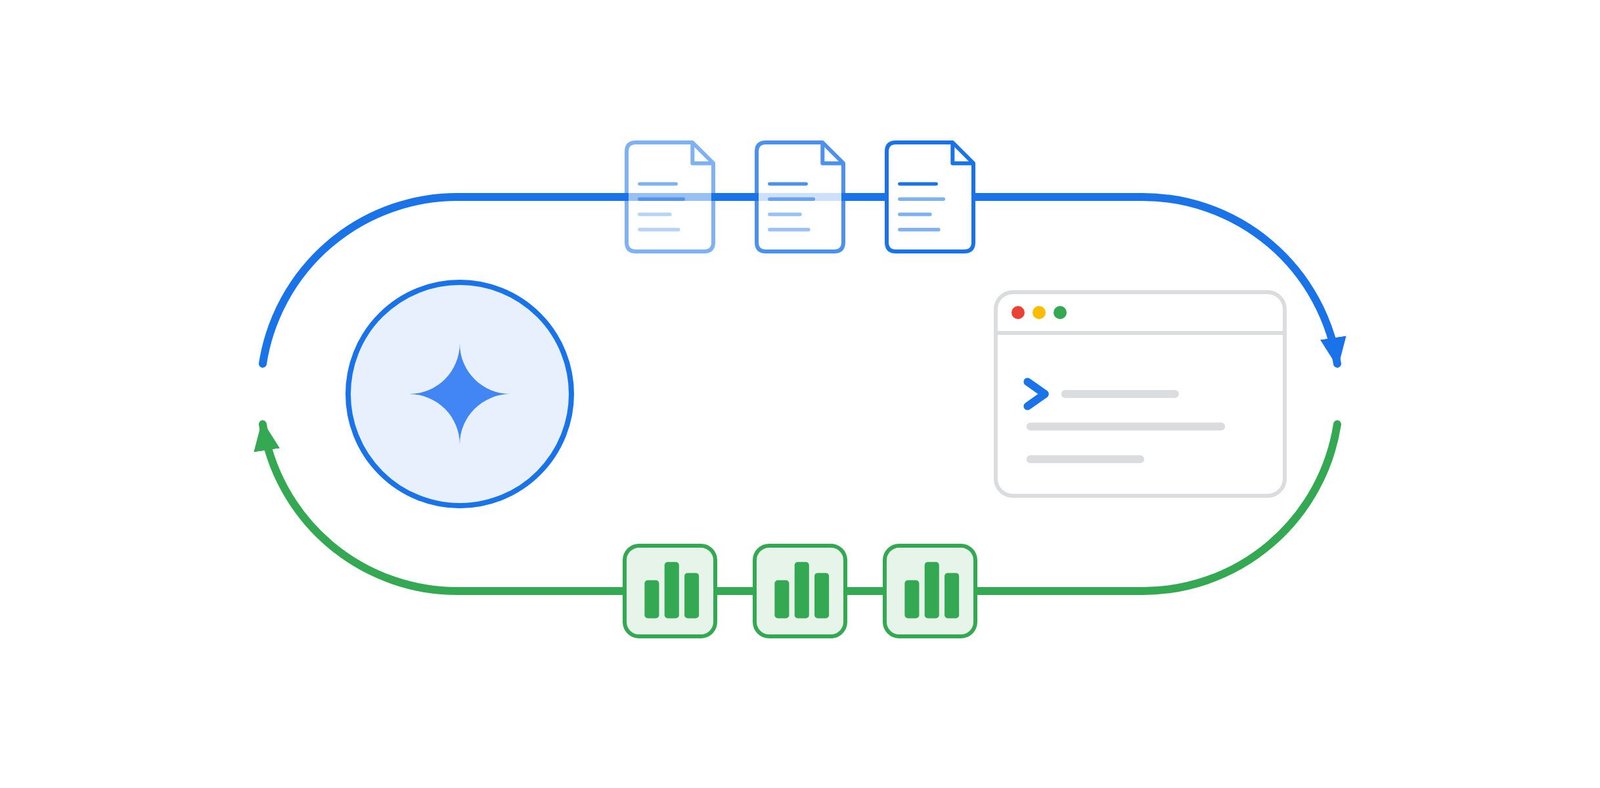
AlphaEvolve focused on the most common failure: running out of time. About a third of the search’s trials hit their time limit, as reported in the evaluator’s notes, and AlphaEvolve’s best skill is built around that limit.
We also found that running the search is harder than building the loop. After about 10 hours, the search scored no new candidate; our latency check held back every evaluation while model responses were slow, and full agent logs filled the controller’s disk. It’s important to plan for slow model windows and for log storage before a long search.
In addition, skills paid off when they added what the agent lacks, as advised by the Agent Skills best practices. Our baseline skill made no measurable difference, while the skill holding the answers added 33 points on the dev tasks.
Our hypothesis: today’s models and coding agents are already tuned for coding work, so general advice has little left to add. If so, the room is in specifics, which a search can find: AlphaEvolve’s best skill is built around the agent’s most common failure, running out of time.
What’s next
We’re testing AlphaEvolve on enterprise agent harnesses — system prompt, policy instructions, and tools — where the agent lacks business rules that a search can add. In one small study on customer service test cases for a fictional bank, AlphaEvolve found and fixed a wrong policy rule we had planted, and carried the fix over to cases it never saw.
Other small studies were mixed, and we’ll share our final results when we’ve completed the full study.
Get started
Thanks for reading! Tell us what your own tests show on LinkedIn or X.