This is the first of a two-part series exploring how Google Cloud is bringing the foundational values of a high-performance parallel filesystem–TB/s throughput, sub-ms latency at high client scale, and POSIX support–to a broader set of use cases and users.
Historically, due to the cost and special purpose nature of parallel filesystems, colder data had to be stored outside of the filesystem and AI developers have had to maintain separate, slower environments for writing code, compiling libraries, and managing repositories. This fragmentation increases the toil of manual data staging, dataset copying, and managing disjointed namespaces.
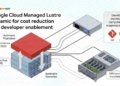
Google Cloud Managed Lustre is solving these problems through our 6 cents/GB*month Dynamic Tier and by optimizing Managed Lustre performance for a range of development tasks and workloads – making Managed Lustre a “One-Stop Shop” for high-performance AI and HPC workloads.
Lower Cost: More Lustre for Less with the Dynamic Tier
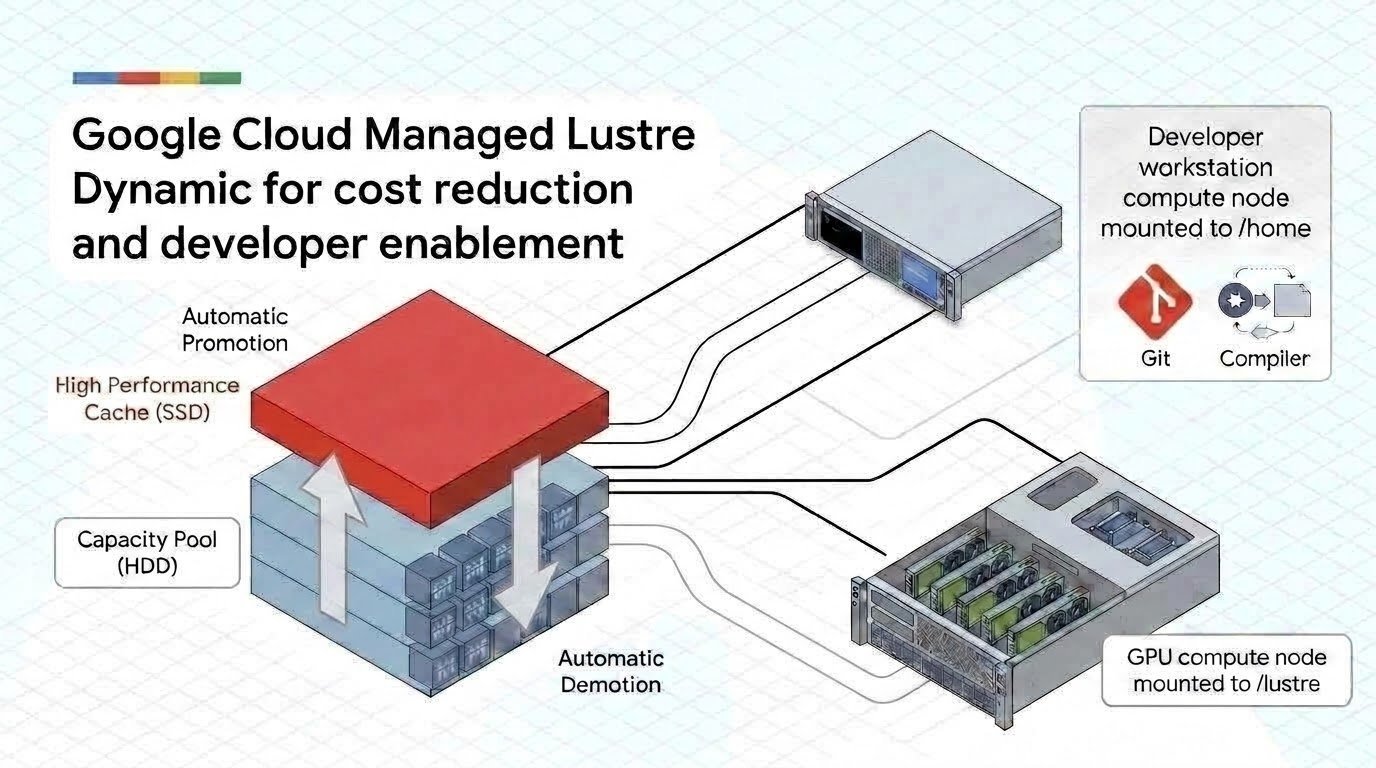
The Managed Lustre Dynamic Tier provides sub-ms latency for hot data, which allows you to store all of your data in a single namespace, and costs only 6 cents/GB*month.
-
Throughput, capacity scale and client scale: Throughput scales linearly with capacity up to 80 PB, while sub-ms latency for hot data remains stable as you scale to tens of thousands of clients.
-
Single-flat fee: Predictable pricing. No independent charges for disk media types, data movement within the namespace, or metadata IOPS.
-
Read Latencies: Sub-ms latencies for High-Performance Cache (SSD). The Capacity Pool (“HDD”) is built on Google Cloud Hyperdisk throughput, which has an average read latency of 10 to 30 ms.
Recommended workloads for Dynamic Tier
-
Multi-Epoch Training and/or Training with Optimized Fetch Sizes: Hot data is promoted to the High Performance Cache (SSD) after the first run. Larger data prefetch will allow you to take advantage of the Dynamic Tier cost structure and gain from low-latency SSD.
-
Write-Heavy Checkpointing: Bursty checkpoint writes land directly in the High Performance Cache. Older checkpoints are transparently demoted to the Capacity Pool (HDD).
-
Rapid Checkpoint Restore: New checkpoints are written to the High Performance Cache, enabling low-latency checkpoint restores.
-
Interactive Snappiness for Developers: Low-latency tasks like git cloning, compiling libraries, or running notebooks benefit from a local-disk feel (~300µs average read latencies) on the same shared workspace hosting large training sets.
Frictionless development: Lustre as a one-stop shop for developer’s workloads
In addition to Managed Lustre’s scalability for large AI and HPC workloads (checkpoint/restart/data-loading), it also meets the demands for interactive work, meaning developers can start on Managed Lustre and stay on Managed Lustre throughout the entire workload lifecycle:
Unified Foundation & Interactive Performance
Consolidates the AI and HPC lifecycle into a single namespace, providing a “local disk” feel for interactive work (Read more about the latency benefits of Managed Lustre experienced by Salesforce and others).
-
Latency: ~300µs average read latency—delivering up to 4x better responsiveness than alternative distributed file systems.
-
Accelerated Setup: Untar the Linux kernel in ~2 minutes (4.7x faster than alternative file solutions), run a 20-worker parallel git clone of Python in ~40 seconds, compile Python in ~200s.